Follow Laplace’s agents across atmospheric dynamics, impact physics and subsurface inference, from configuring simulators to comparing the worlds they produce.
Six scientific studies sit alongside three engineering notes and one unresolved CFD investigation. They record scenario setup, parallel runs, diagnostics and visual outputs, making the component capabilities behind Laplace’s Physical AI ambition concrete.
10 recorded sessions: 6 scientific studies, 3 engineering notes, and 1 unresolved CFD investigation. These are demonstrations of computational work, not measured customer outcomes.
Model inputs + numerical outputs + explanations + next experiments
Editorial grouping of related capabilities, not a proven serial dependency graph. Sessions overlap; the exports do not establish that every later study reused an unchanged earlier specialist.
How Laplace carried the project work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Assemble environments
→
Task 2Learn each solver
→
Task 3Configure + run
→
Task 4Reconcile outputs
→
Task 5Prepare explanations
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
A CESM test with dead model components advances one model day through 48 coupler steps and records restart output. The supplied report provides the acceptance record.
Infrastructure smoke test with dead model components. No climate finding is claimed.
Pressure-wave amplitude grows from 0.2323 to 49.7354 hPa between model days one and ten. The diagnostic tables connect that growth to ascent, cloud water and rainfall in the idealized atmosphere.
Idealized model dynamics. The 214× figure measures pressure-wave growth, not computational speed or forecast accuracy.
A month of model weather leaves a reusable record.
A three-hourly record follows the atmosphere from model day zero through day 31. The saved time series, jet table, charts and film let the evolution be inspected beyond a single viewing.
Simulated duration, not elapsed work. The original lifecycle figure retains a stale pressure label; this is not a real-world forecast.
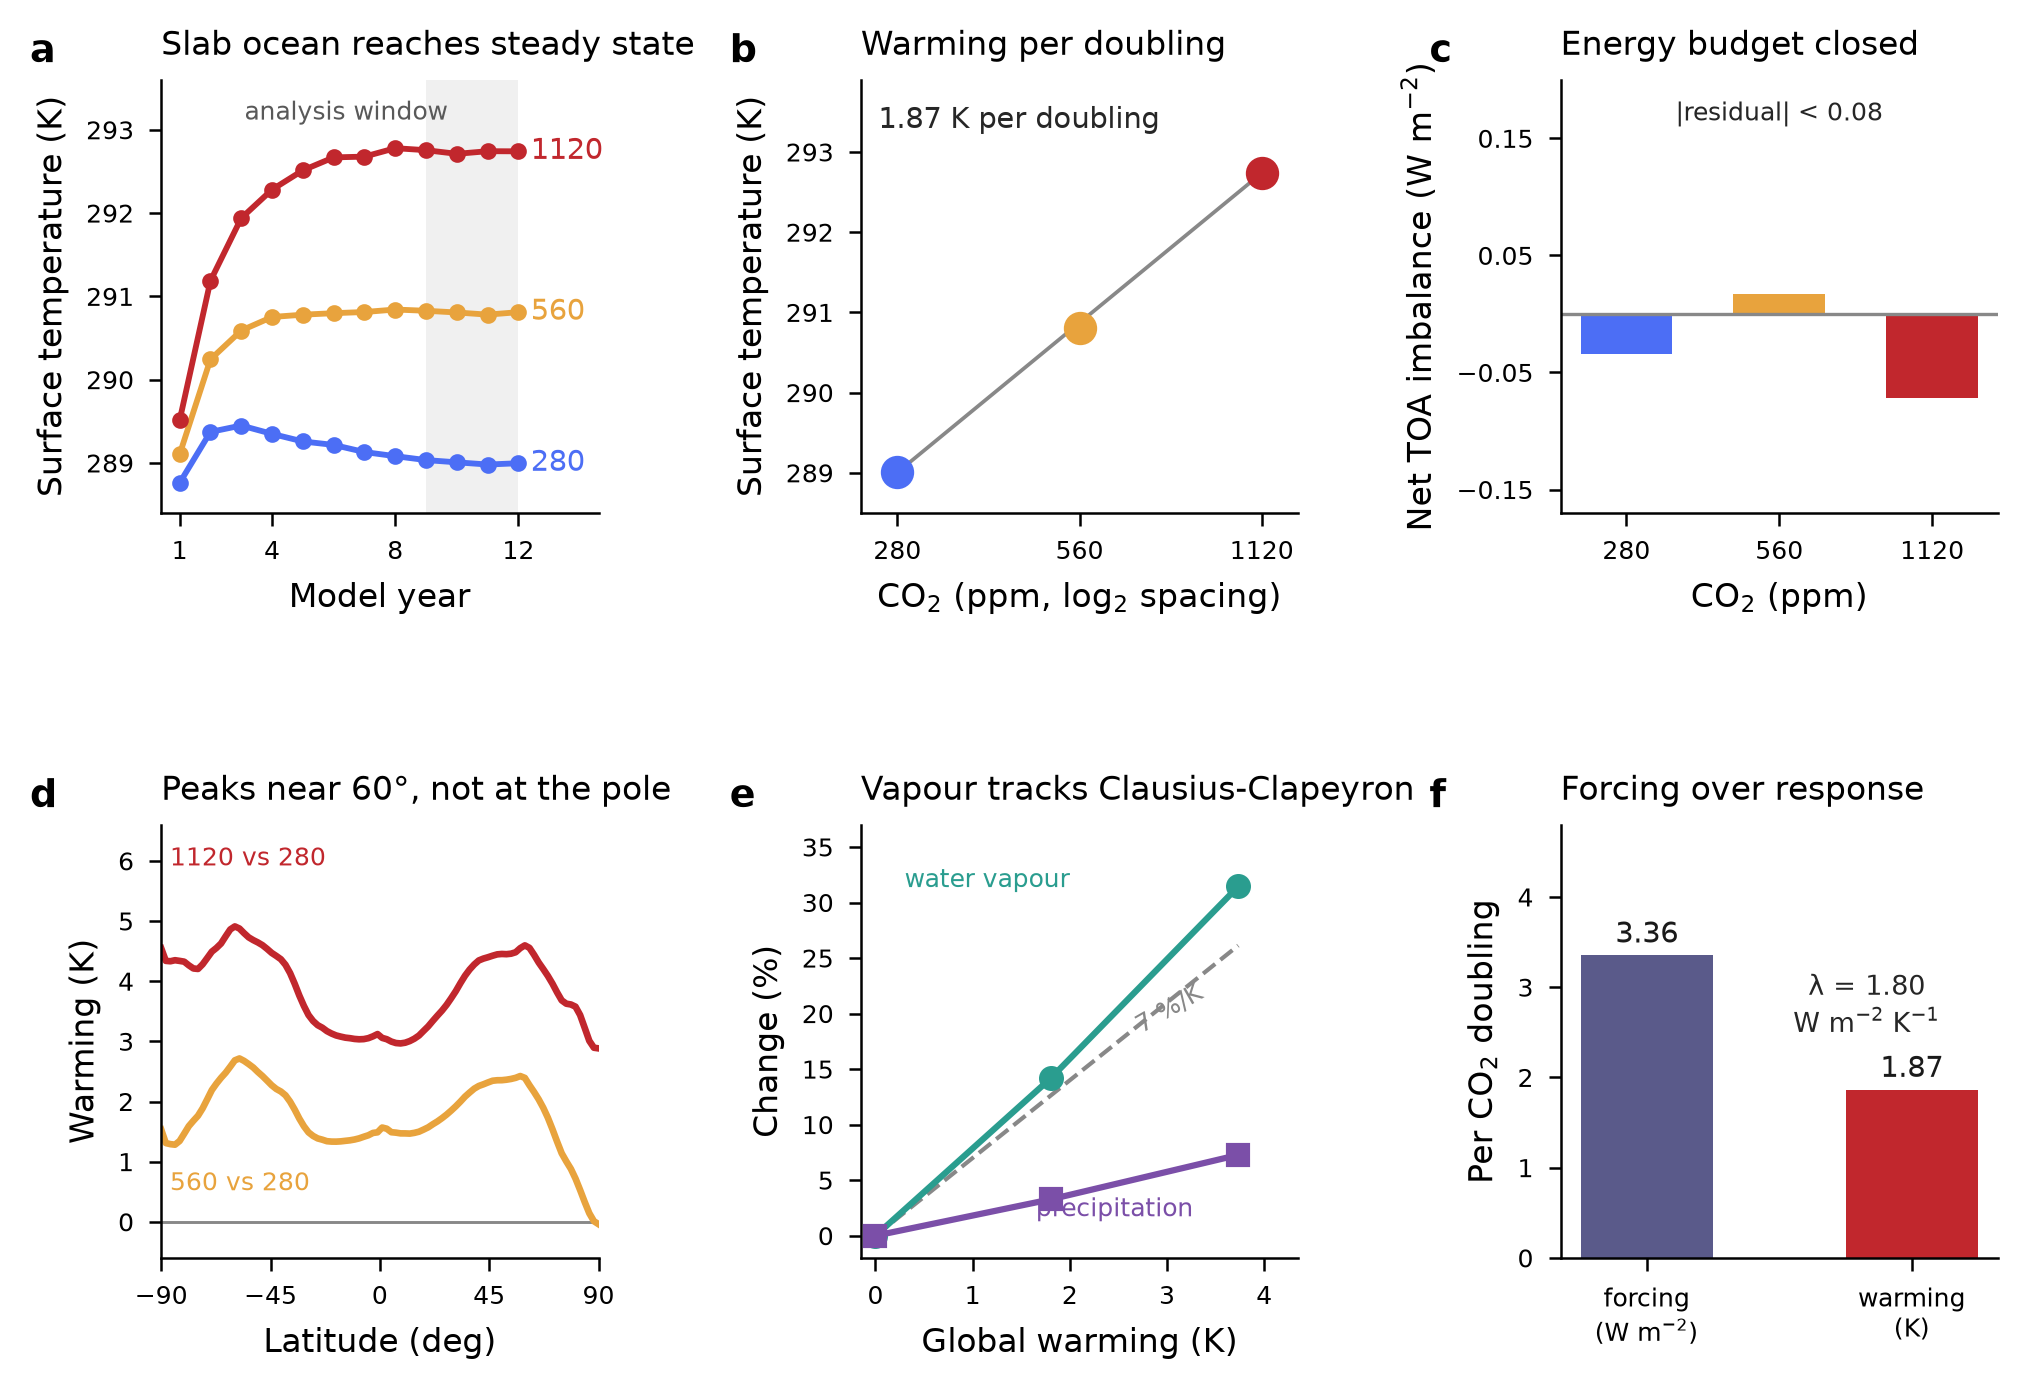
The fixed-temperature runs isolate an energy response, while the 30 m slab-ocean runs allow warming. The approximate 1.87 K response per CO₂ doubling belongs to this idealized aquaplanet.
Idealized aquaplanet with a 30 m slab ocean, without realistic land, sea ice, seasons, or ocean circulation. These responses are not an Earth climate-sensitivity estimate.
The historical discussion compares elastic compute resources with the existing scientific cluster. It provides workload questions, without a simulation or matched performance benchmark.
No simulation or matched performance benchmark. Historical hardware and pricing claims are not current buying advice.
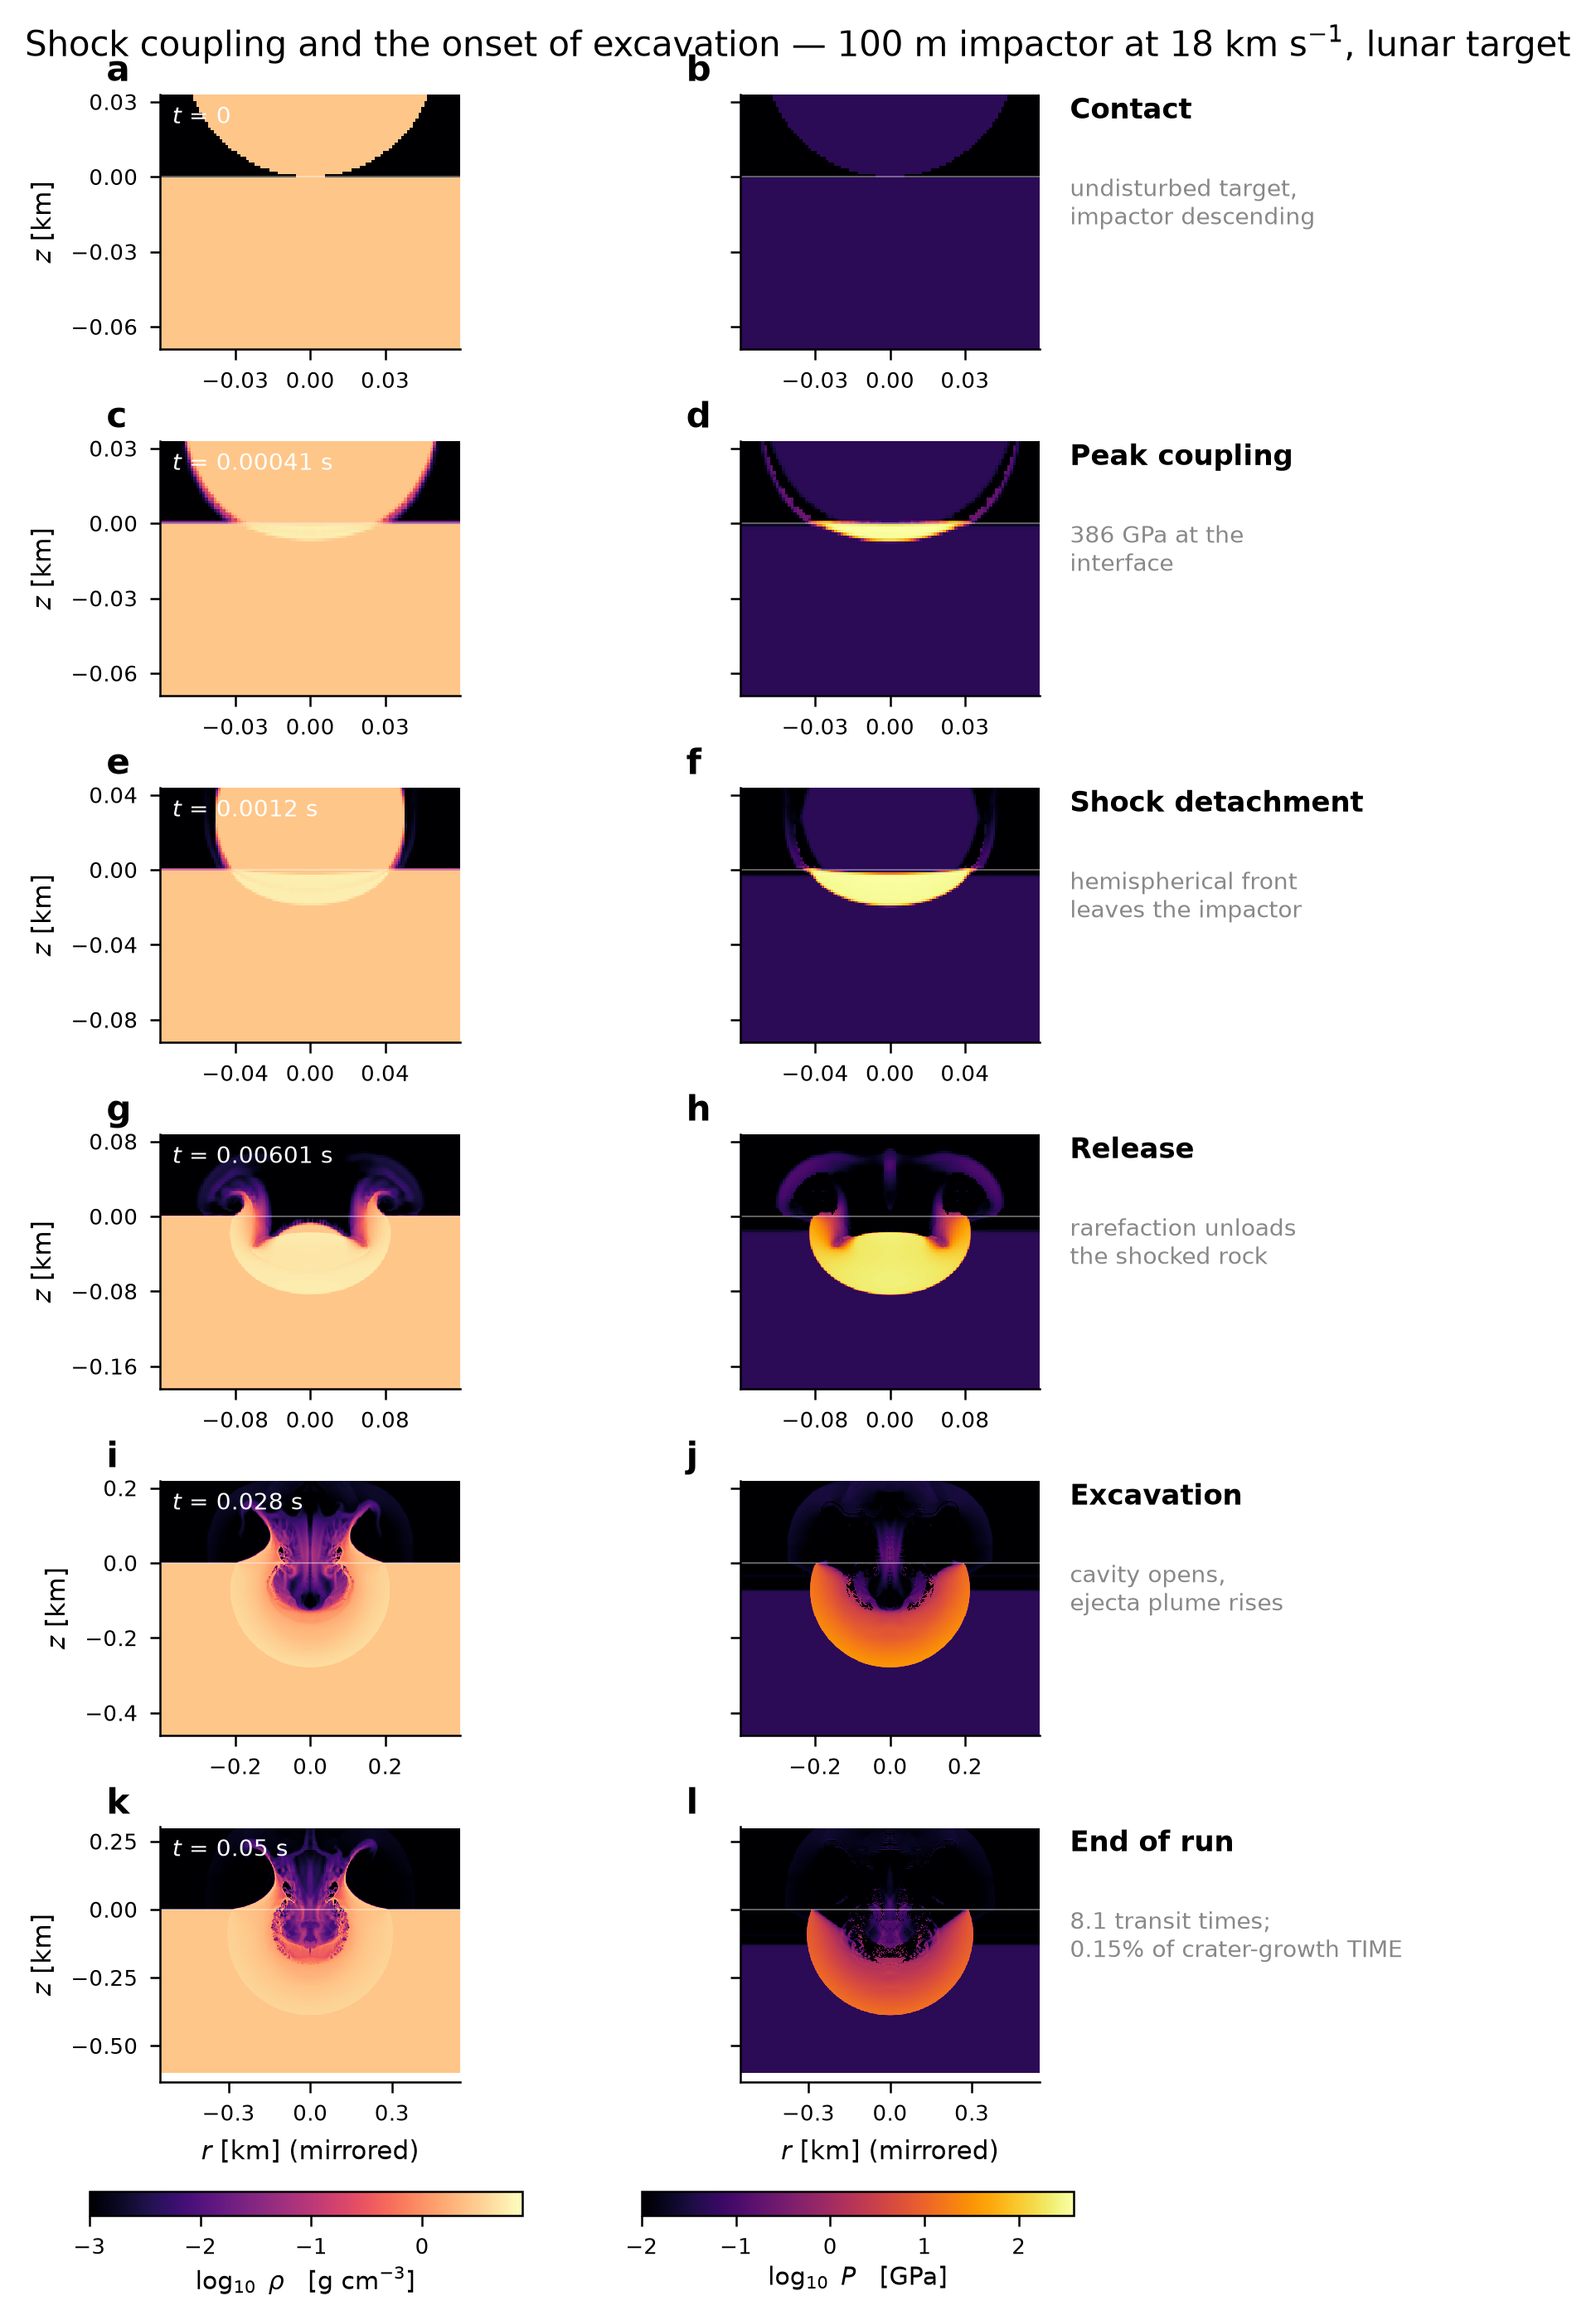
The early-impact calculation reaches a peak pressure of 385.7 GPa against a 391.4 GPa analytic reference. It stops at 0.05 seconds; a final-crater estimate comes from a separate scaling law.
The impact simulation ends at 0.05 seconds. The final-crater estimate comes from a separate scaling law; the stellar example is an idealized toy.
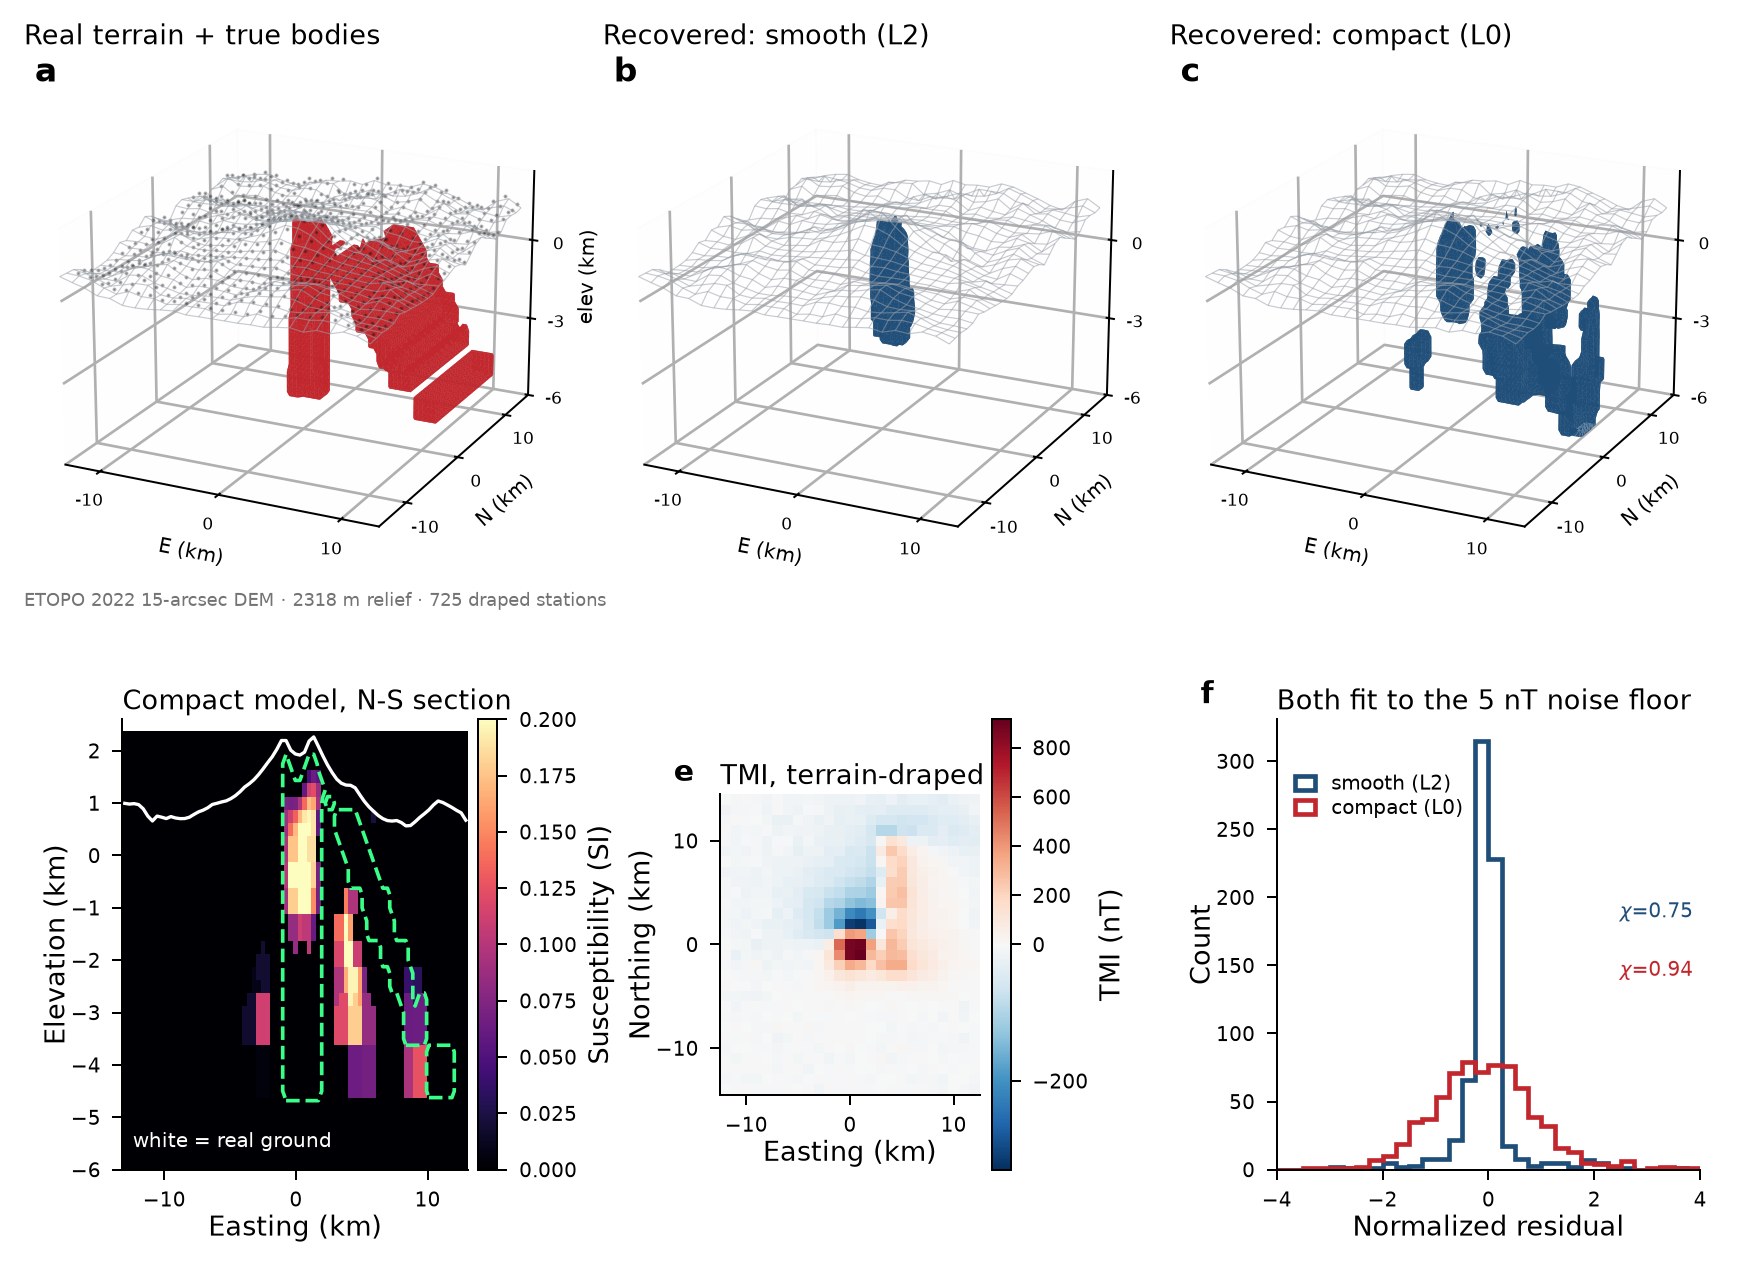
Smooth and compact inversions both fit the synthetic magnetic signal while placing susceptibility differently underground. Their disagreement makes the need for another constraint visible.
Synthetic magnetic observations and buried structures over real terrain. Fit ratios are not reconstruction-accuracy percentages.
After real-data access failed, a 529-station synthetic study recovered mass 5.02% above the constructed truth. A near-target data-misfit ratio of 1.012 still left the bed-depth geometry unresolved.
Synthetic substitute after real-data acquisition failed. The original figure retains a misleading BedMachine label; depth recovery remains unresolved.
A 51,300-cell case also fails, challenging the explanation that fine-grid geometry alone caused the problem. The later run still has unacceptable residuals and roughly 50% mass imbalance, so no entrainment ratio is accepted.
No accepted entrainment ratio. A transient-solver alternative was proposed but not run successfully in this record.
Run a minimal one-day CESM infrastructure test with dead components, checking case creation, compilation, submission, time-stepping and output recovery.Run a minimal one-day CESM infrastructure test with dead components, checking case creation, compilation, submission, time-stepping and output recovery.Run a minimal one-day CESM infrastructure test with dead components, checking case creation, compilation, submission, time-stepping and output recovery.
Research prompt↑
LLaplaceRecorded result
One completed build-to-output check.
A CESM test with dead model components advances one model day through 48 coupler steps and records restart output. The supplied report provides the acceptance record.
The test uses dead components and establishes no climate finding. The supplied bundle contains a report rather than raw run logs or a complete reconstruction package.
An edited brief introduces the recorded investigation. Read the source prompt below for its original context and later steering.
Read the research prompt
Research prompt · edited for public presentation
Run a minimal CESM infrastructure test: compset X with dead model components, resolution f19_g17, and a one-day run. Create the case, build it, submit it, confirm time-stepping and summarize the output.
A large scientific run is a poor place to discover that compilation, job submission or output collection is broken.
01
Specify a minimal acceptance test
The user explicitly requested dead model components and one model day, to prove the pipeline rather than perform science.
02
Build, submit and inspect
The supplied report records case creation, a 289-second build, cluster submission and 48 coupler steps of 1,800 seconds.
03
Leave a bounded infrastructure receipt
The report records a 35-second model execution and restart output. A claim that the case name automatically selected test mode was retracted.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Define acceptance
→
Task 2Configure CESM
→
Task 3Build + submit
→
Task 4Inspect logs
→
Task 5Record the result
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Build caseCompile + submitInspect + report
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
Setup work delegatedCase creation, build, submission and inspection are captured together.
An early failure gateThe minimal run checks infrastructure before a larger science workload.
Reusable acceptance recordThe report makes the successful path and its limits inspectable.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Build case. The user explicitly requested dead model components and one model day, to prove the pipeline rather than perform science.
Compile + submit. The supplied report records case creation, a 289-second build, cluster submission and 48 coupler steps of 1,800 seconds.
Inspect + report. The report records a 35-second model execution and restart output. A claim that the case name automatically selected test mode was retracted.
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
00h 39m 32sCalendar span of the conversation
3mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
This is an infrastructure smoke test with dead components, not a climate simulation.
The ZIP supplies a report, not the raw logs or a complete reconstruction package.
The report retracts the automatic run-type claim; registry upload was not completed.
The next useful decision
Move to a real-physics configuration and verify its input data and output fields before scaling the workload.
Run a small CESM atmosphere, extend it to reveal the growth of a disturbance, and explain the evolving weather with diagnostics and a film.Run a small CESM atmosphere, extend it to reveal the growth of a disturbance, and explain the evolving weather with diagnostics and a film.Run a small CESM atmosphere, extend it to reveal the growth of a disturbance, and explain the evolving weather with diagnostics and a film.
Research prompt↑
LLaplaceRecorded result
Ten days of growth, with the numbers behind the film.
Pressure-wave amplitude grows from 0.2323 to 49.7354 hPa between model days one and ten. The diagnostic tables connect that growth to ascent, cloud water and rainfall in the idealized atmosphere.
This is idealized atmospheric dynamics, not a forecast or an observational validation. The films cover days 0–10 of the longer run, and the roughly 214× growth is pressure amplitude rather than a computational speedup.
Original corrected chart. Daily-mean cloud-water maxima remain below the plotted 1,000 mg/kg threshold.
How the investigation developed.
Getting a model to finish is only the first step. Someone still has to identify the mechanism, extract the right quantities and make the result understandable.
01
Run an idealized physical atmosphere
The initial request was a one-day FKESSLER test. The discussion then extended the run and requested a ten-day 3D explanation.
02
Measure the disturbance as it grows
The supplied lifecycle CSV tracks pressure-wave amplitude, ascent, cloud water and rain. Day 1 to day 10 pressure amplitude grows from 0.2323 to 49.7354 hPa.
03
Correct the explanation
Review corrected a misleading growth-time caption and the treatment of the initial snapshot. Final charts distinguish pressure growth from ascent growth and avoid a false cloud-threshold crossing.
04
Package the scientific story
The record includes CSVs, a model history file, charts, a globe artifact and two original explanatory movies.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Configure atmosphere
→
Task 2Run the model
→
Task 3Extract diagnostics
→
Task 4Explain the mechanism
→
Task 5Create the movie
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Run atmosphereExtract diagnosticsCorrect explanationProduce movies
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
Execution + explanation connectedA solver run becomes a numerical and visual account in the same record.
Revisions carried throughGrowth definitions and misleading captions were challenged during production.
A reusable evidence packageThe handoff includes both the explanation and the values behind it.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Run atmosphere. The initial request was a one-day FKESSLER test. The discussion then extended the run and requested a ten-day 3D explanation.
Extract diagnostics. The supplied lifecycle CSV tracks pressure-wave amplitude, ascent, cloud water and rain. Day 1 to day 10 pressure amplitude grows from 0.2323 to 49.7354 hPa.
Correct explanation. Review corrected a misleading growth-time caption and the treatment of the initial snapshot. Final charts distinguish pressure growth from ascent growth and avoid a false cloud-threshold crossing.
Produce movies. The record includes CSVs, a model history file, charts, a globe artifact and two original explanatory movies.
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
17h 02m 21sCalendar span of the conversation
55mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
214× is atmospheric amplitude growth, not a computational speedup.
Day 0 is an instantaneous state; daily averages begin later and should not be mixed into the same growth calculation.
Peak rain near 55 mm/day is local; day-10 area-mean rain is about 0.0096 mm/day.
No physical validation or conventional-workflow timing was supplied.
The next useful decision
Test sensitivity to the initial conditions and resolution, then check the explanation against independent diagnostics.
A month of model weather leaves a reusable record.
The question. The result.
Weather modellingRecorded investigation
YYouEdited research brief
Run a simple month-long CESM experiment that reveals interesting atmospheric physics with little spinup, then explain its evolution.Run a simple month-long CESM experiment that reveals interesting atmospheric physics with little spinup, then explain its evolution.Run a simple month-long CESM experiment that reveals interesting atmospheric physics with little spinup, then explain its evolution.
Research prompt↑
LLaplaceRecorded result
31 model days. 249 diagnostic samples.
A three-hourly record follows the atmosphere from model day zero through day 31. The saved time series, jet table, charts and film let the evolution be inspected beyond a single viewing.
The experiment omits radiation, an evolving ocean and surface friction, so it is not a climate equilibrium or forecast. The original lifecycle figure and jet-pressure label retain inconsistencies identified in the evidence summary.
A month of model weather becomes 249 saved snapshots, diagnostic curves and an explanatory film.
The 94-second clock measures model execution on 24 cores. It excludes the roughly 10-minute build, analysis and animation. This is idealized weather, not a forecast.
Watch the result Original session films
One month of model weather1m 23.4s playback
Original movie. Its simulation clock is independent of the session clock.
Playback length is separate from simulated time and the session span.
Two clocks · one precisely scoped run
A month inside the model. A different clock outside.
The physical timeline and the execution receipt answer different questions.
31 daysinside the simulated atmosphere
94 secondsrecorded execution · 24 cores
A simplified atmosphere evolves across 31 model days. Its saved diagnostic series contains 249 samples at three-hour intervals.
The 94-second receipt covers the model run. It does not include the build, analysis or the explanatory film.
The build was reported at roughly 10 minutes. Analysis and rendering followed; no total active-work clock or human-hours saving is established.
The work behind the result
Follow the investigation.
Use the requested simple, low-spinup experiment with idealized FKESSLER dynamics.
Advance the experiment through 31 simulated days.
Extract 249 three-hourly rows and the separate zonal-jet table.
Retain the two charts, explainer script and original movie alongside the numerical data.
Condensed from the recorded investigation, including later steering and review. Playback does not represent elapsed time.
31 model daysSimulated duration, not elapsed labourSource
249 samplesThree-hourly rows from day 0 through 31Source
How the investigation developed.
The task is to turn an initial-value experiment into a readable lifecycle, rather than deliver an unexplained directory of model output.
01
Choose a bounded demonstration
The user asked for a simple one-month run with interesting physics and little spinup. The recorded configuration uses idealized FKESSLER dynamics.
02
Extract a month of evolution
The supplied timeseries has 249 three-hourly rows from model day 0 through day 31, plus a separate zonal-jet table.
03
Produce the visual handoff
The six supplied files include an explainer script, two CSVs, two charts and the original movie.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Choose a test case
→
Task 2Run one month
→
Task 3Extract time series
→
Task 4Review the lifecycle
→
Task 5Render an explanation
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Choose configurationExtract month of dataProduce a film
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
Run-to-film work delegatedThe model output, diagnostics and explanation are assembled in one session.
A reusable time seriesThe numerical record can support a revised explanation without another run.
Quality issues made visibleThe reader flags stale figure values instead of promoting them.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Choose configuration. The user asked for a simple one-month run with interesting physics and little spinup. The recorded configuration uses idealized FKESSLER dynamics.
Extract month of data. The supplied timeseries has 249 three-hourly rows from model day 0 through day 31, plus a separate zonal-jet table.
Produce a film. The six supplied files include an explainer script, two CSVs, two charts and the original movie.
Original figure retained unchanged. Its final 872 hPa label is stale: the supplied timeseries gives approximately 880.48 hPa at day 31.How to read the timing
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
02h 45m 10sCalendar span of the conversation
27mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
This finite initial-value experiment omits radiation, an evolving ocean and surface friction; it is not a climate equilibrium or forecast.
The original lifecycle figure contains a stale final-pressure label.
The jet CSV refers to 250 hPa, while the source diagnosis identifies a level near 233 hPa.
The recorded 94-second model execution excludes the approximately 10-minute build, analysis and rendering. It does not measure human time saved.
The next useful decision
Align the original figure and pressure-level labels with the final numerical data, then use the saved series to test a further question.
Give scientific results a working route to animation.
The question. The result.
Scientific visualizationRecorded investigation
YYouEdited research brief
Create a Manim visualization specialist and test that its environment can render a short scene for explaining scientific results.Create a Manim visualization specialist and test that its environment can render a short scene for explaining scientific results.Create a Manim visualization specialist and test that its environment can render a short scene for explaining scientific results.
Research prompt↑
LLaplaceRecorded result
An animation toolchain passes its first render test.
A configured Manim environment produces a short test movie and retains its scene source. The result verifies a recorded render path.
This is a rendering setup check with no physical simulation or scientific finding. Later animations do not establish unchanged reuse of this exact historical specialist profile.
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
Repeated setup addressedThe recorded profile packages a visualization role for reuse.
A tested output pathThe smoke movie demonstrates that the environment could render.
Communication capability addedLater studies in the project also produce scientific movies.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Define specialist. The user requested a new Manim visualization specialist and supplied a skill attachment.
Configure renderer. The record describes a specialist profile and environment, then tests rendering with a short scene. Missing LaTeX support required a text fallback.
Test + retain output. The supplied files are the test scene and its short MP4. The attachment itself is absent from this ZIP.
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
00h 05m 46sCalendar span of the conversation
2mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
No physical simulation or scientific finding was produced in this session.
The source attachment is not supplied; the historical profile description is not a complete current deployment package.
Later Manim outputs demonstrate the same kind of capability but do not prove unchanged reuse of this exact profile.
The next useful decision
Test the workflow on a known numerical dataset and check that the explanation preserves the quantities, units and model limits.
Use CESM to compare higher CO₂ levels, first holding ocean temperature fixed and then letting a simple ocean warm, so the energy change and temperature response can be separated.Use CESM to compare higher CO₂ levels, first holding ocean temperature fixed and then letting a simple ocean warm, so the energy change and temperature response can be separated.Use CESM to compare higher CO₂ levels, first holding ocean temperature fixed and then letting a simple ocean warm, so the energy change and temperature response can be separated.
Research prompt↑
LLaplaceRecorded result
Three CO₂ levels. Two ocean setups. Six experiments.
The fixed-temperature runs isolate an energy response, while the 30 m slab-ocean runs allow warming. The approximate 1.87 K response per CO₂ doubling belongs to this idealized aquaplanet.
The aquaplanet has a 30 m slab ocean and lacks realistic land, sea ice, seasons and ocean circulation. Its response is not an estimate of Earth’s climate sensitivity.
Three CO₂ settings reuse one compiled model. Two cases run concurrently, then the third starts when a node becomes free.
About 24 minutes from submission to completion for the three fixed-ocean-temperature cases, including boot and queue time. The separate slab-ocean runs, setup and analysis are outside this clock.
3.36 W/m²Approximate forcing increment per CO₂ doubling in this setupSource
1.87 KApproximate warming per doubling in this idealized slab-ocean setupSource
Explore recorded results · 6 completed model runs
Turn up the CO₂. What changes?
Choose a concentration and an experiment. The display switches between the actual saved results, with the physical assumptions kept visible.
Which question are we asking?
Temperature rise relative to 280 ppm (K)
Dots are the three saved runs. The dashed connector is a visual guide; intermediate concentrations were not simulated here.
Warming vs 280 ppm+1.80 KSlab-ocean equilibrium comparison
Mean model surface temperature17.66 °CYears 9–12 of a 12-year model run
This is an idealized aquaplanet. The slab ocean is 30 m deep; there is no realistic land, sea ice, seasons or ocean circulation. These are conditional model responses, not an Earth climate-sensitivity estimate.
How the investigation developed.
A convincing warming chart needs a controlled experiment. Changing a setup label is not enough: the actual radiation input must receive the intended CO₂ value.
01
Turn a broad request into controlled experiments
After the user specified CESM, the study compared 280, 560 and 1,120 ppm in two setups: fixed sea-surface temperature and a 30 m slab ocean.
02
Verify the setting reaches the physics
The record identified a parameter-propagation issue and checked co2vmr in the atmosphere input. Otherwise different case labels could represent the same radiative input.
03
Separate forcing from warming
Fixed-SST experiments ran 14 model months; slab-ocean experiments ran 12 model years. The selected analysis uses the final 12 months and years 9–12 respectively.
04
Deliver an interpretable comparison
Two diagnostic tables, two original figures, reduced model files, explanatory movies and a five-page report carry the experiment into a reviewable handoff.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Design controls
→
Task 2Configure six cases
→
Task 3Run both setups
→
Task 4Compare diagnostics
→
Task 5Write + visualize
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Build six casesVerify CO₂ inputCompare responsesPackage the study
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
A matrix of experiments from one briefSix configured runs replace separate manual assembly of each comparison.
Input verification inside the loopThe CO₂ setting was checked where it enters the actual atmosphere model.
Analysis + communication packagedTables, original figures, movies and a report share the same study record.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Build six cases. After the user specified CESM, the study compared 280, 560 and 1,120 ppm in two setups: fixed sea-surface temperature and a 30 m slab ocean.
Verify CO₂ input. The record identified a parameter-propagation issue and checked co2vmr in the atmosphere input. Otherwise different case labels could represent the same radiative input.
Compare responses. Fixed-SST experiments ran 14 model months; slab-ocean experiments ran 12 model years. The selected analysis uses the final 12 months and years 9–12 respectively.
Package the study. Two diagnostic tables, two original figures, reduced model files, explanatory movies and a five-page report carry the experiment into a reviewable handoff.
Original slab-ocean figure. The temperature response is conditional on this simplified world.How to read the timing
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
21h 19m 49sCalendar span of the conversation
8h 14mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
The aquaplanet has no realistic land, sea ice, seasons or ocean circulation. Its 1.87 K response is not an estimate of Earth’s climate sensitivity.
The maximum absolute final slab-ocean energy imbalance is about 0.072 W/m²; that is a model diagnostic, not real-world validation.
A five-page article and persuasive movie do not independently establish predictive accuracy.
The record includes human direction and revisions; human effort and compute costs were not measured as a matched baseline.
The next useful decision
Repeat with richer physical components and independent validation before using the response for an Earth-system prediction.
Compare available compute environments for CPU and high-performance scientific workloads, and identify what would need to be measured before choosing between them.Compare available compute environments for CPU and high-performance scientific workloads, and identify what would need to be measured before choosing between them.Compare available compute environments for CPU and high-performance scientific workloads, and identify what would need to be measured before choosing between them.
Research prompt↑
LLaplaceRecorded result
A resource comparison leaves a benchmark to run.
The historical discussion compares elastic compute resources with the existing scientific cluster. It provides workload questions, without a simulation or matched performance benchmark.
No simulation or matched benchmark was executed in this session. Historical hardware and pricing descriptions do not establish current availability or a faster, cheaper provider.
General hardware specifications are easy to mistake for a measured performance advantage on a particular model.
01
Ask what resources are available
The user asked about Modal’s compute, then narrowed the question to CPU and HPC hardware comparisons.
02
Frame the workload tradeoff
The discussion compares elastic resources with the existing cluster. It supplies a historical narrative, not a benchmark run.
03
Separate useful research from unsupported claims
Source review flagged unsupported statements about an unrelated cluster task. Those statements are excluded from the evidence used here.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Collect specifications
→
Task 2Map workloads
→
Task 3Compare constraints
→
Task 4Verify claims
→
Task 5Record a decision
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Research resourcesCompare workloadsQualify the claims
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
A decision frame gatheredCompare resource fit before choosing by headline specifications.
Research kept with the projectThe discussion remains discoverable alongside the workloads.
No invented outputThe reader preserves the source response without fabricating a chart or speed claim.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Research resources. The user asked about Modal’s compute, then narrowed the question to CPU and HPC hardware comparisons.
Compare workloads. The discussion compares elastic resources with the existing cluster. It supplies a historical narrative, not a benchmark run.
Qualify the claims. Source review flagged unsupported statements about an unrelated cluster task. Those statements are excluded from the evidence used here.
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
00h 37m 51sCalendar span of the conversation
6mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
This is research, not a simulation. Hardware offers and prices in the historical discussion are not current recommendations.
The session does not establish that Modal is faster, cheaper or suitable for a specific MPI workload.
Review flagged unsupported claims about a separate task; the record is not proof of reliable unattended coordination.
The next useful decision
Benchmark the same workload and configuration on the candidate environments, including elapsed time, cost and data-transfer overhead.
Set up Castro experiments, then model the early impact of a 100 m rock striking the Moon at 18 km/s and compare the shock with an analytic reference.Set up Castro experiments, then model the early impact of a 100 m rock striking the Moon at 18 km/s and compare the shock with an analytic reference.Set up Castro experiments, then model the early impact of a 100 m rock striking the Moon at 18 km/s and compare the shock with an analytic reference.
Research prompt↑
LLaplaceRecorded result
The first 50 milliseconds, with a pressure check.
The early-impact calculation reaches a peak pressure of 385.7 GPa against a 391.4 GPa analytic reference. It stops at 0.05 seconds; a final-crater estimate comes from a separate scaling law.
The impact run covers only the early 0.05 seconds and does not simulate the final crater. The separate stellar-layer example omits magnetic physics and does not model a solar coronal mass ejection.
Adaptive refinement concentrates resolution around the shock while parallel processors advance the impact model and record its evolution.
Recorded runtime for the final early-impact run, covering 0.05 physical seconds. Preparation, physics corrections, validation and movies are outside this clock.
Original early-impact snapshots. The evolving cavity is not a final crater.
How the investigation developed.
Starting from a new solver requires environment knowledge, problem setup, numerical debugging, diagnostics and communication.
01
Chapter 1 · create a specialist and test an instability
The session starts with a Castro specialist, then demonstrates Rayleigh–Taylor instability in 2D and 3D: heavy fluid falling through lighter fluid.
02
Chapter 2 · explore a stellar-layer toy
An imposed heat pulse drives motion in a two-dimensional plane-parallel atmosphere. The output measures material leaving the computational top boundary. It is not a magnetized solar-ejection model.
03
Chapter 3 · simulate a lunar impact’s early shock
A 100 m rock strikes at 18 km/s in a 2D axisymmetric setup with a custom equation of state. The calculation covers only the first 0.05 seconds.
04
Compare and qualify the output
The recorded impact peak pressure is about 385.7 GPa versus a 391.4 GPa analytic reference. A 2.21 km final crater estimate comes from a scaling law, not the short simulation.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Learn Castro
→
Task 2Configure problems
→
Task 3Run + debug
→
Task 4Audit diagnostics
→
Task 5Write reports
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Build + test CastroRun stellar toyRun impact studyCompare + qualify
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
A solver setup reused within a sessionThe record moves from capability setup into several explicit study requests.
Diagnostics carried into reportsImages, numerical metrics and two papers accompany the demonstrations.
Model boundaries made explicitEarly shock, domain mass loss and scaling estimates remain separate claims.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Build + test Castro. The session starts with a Castro specialist, then demonstrates Rayleigh–Taylor instability in 2D and 3D: heavy fluid falling through lighter fluid.
Run stellar toy. An imposed heat pulse drives motion in a two-dimensional plane-parallel atmosphere. The output measures material leaving the computational top boundary. It is not a magnetized solar-ejection model.
Run impact study. A 100 m rock strikes at 18 km/s in a 2D axisymmetric setup with a custom equation of state. The calculation covers only the first 0.05 seconds.
Compare + qualify. The recorded impact peak pressure is about 385.7 GPa versus a 391.4 GPa analytic reference. A 2.21 km final crater estimate comes from a scaling law, not the short simulation.
Original figure. About 1.76% mass leaving the open top is domain loss, not evidence that material escaped the Sun.How to read the timing
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
1d 00h 05m 55sCalendar span of the conversation
6h 20mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
These are three chapters in one session, not three independent customer successes.
The stellar toy omits magnetic fields and does not model a solar coronal mass ejection.
The impact calculation ends before final crater formation; the 2.21 km estimate is a separate scaling-law result.
Equation-of-state, diagnostic, literature and audit issues were revised during the record. The supplied reports are not an independent validation or a fully reconciled reproducibility package.
Melt thresholds and mass estimates involve additional assumptions; the reader does not promote them as verified physical predictions.
The next useful decision
Reconcile the final material inputs and diagnostics, then validate the intended impact regime against an independent benchmark before extending the calculation.
Using real terrain and synthetic magnetic observations, compare smooth and compact reconstructions to see whether different underground structures can fit the same survey.Using real terrain and synthetic magnetic observations, compare smooth and compact reconstructions to see whether different underground structures can fit the same survey.Using real terrain and synthetic magnetic observations, compare smooth and compact reconstructions to see whether different underground structures can fit the same survey.
Research prompt↑
LLaplaceRecorded result
108,484 cells. Two plausible reconstructions.
Smooth and compact inversions both fit the synthetic magnetic signal while placing susceptibility differently underground. Their disagreement makes the need for another constraint visible.
The terrain is real, but the buried structures and magnetic observations are synthetic. Misfit ratios describe fit under an assumed noise model, not the probability that the reconstructed geology is correct.
A terrain-aware model creates 725 synthetic observations, then solves the same inverse problem with both smooth and compact assumptions.
Recorded computation over real Mount St Helens terrain, with synthetic magnetic observations. The 108 seconds excludes research iterations and animation; different subsurface models can fit the same data.
Watch the result Original session films
Inspect the 3D reconstruction6s playback
A rotating view of the Mount St Helens experiment: real terrain, 725 synthetic survey stations, and smooth versus compact reconstructions. The underground structures and magnetic observations are constructed, not field measurements.
Why fitting the signal is not enough1m 6.5s playback
A Manim explainer from the earlier 441-station synthetic experiment in this session. It combines schematic geometry with recorded SimPEG results to explain why different underground models can fit the signal. This is a different example from the 725-station terrain study.
Original figure compares the known constructed bodies with smooth and compact reconstructions. It is not a discovery beneath Mount St Helens.
How the investigation developed.
A visually convincing underground reconstruction can hide a dependence on modelling assumptions and regularization.
01
Build and test the SimPEG capability
Laplace built a SimPEG workflow, starting with numerical checks and synthetic magnetic examples before moving to a three-dimensional terrain model.
02
Place an experiment on real terrain
The Mount St Helens example uses NOAA ETOPO terrain and a specified IGRF field, but its subsurface bodies and magnetic anomaly are synthetic.
03
Compare two valid-looking answers
A smooth and a compact inversion both fit the constructed signal while distributing susceptibility differently underground.
04
Explain non-uniqueness
Original figures and movies visualize what changes between the models. Review corrected a misfit-target definition and an earlier illustrative animation trace.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Acquire terrain
→
Task 2Construct a survey
→
Task 3Configure inversions
→
Task 4Compare models
→
Task 5Explain ambiguity
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Test SimPEGBuild terrain modelCompare inversionsExplain uncertainty
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
Multiple models compared in one workflowTwo inversion choices expose what a single polished reconstruction would conceal.
Data + geometry assembledReal topography is brought into a controlled synthetic experiment.
A decision-ready uncertainty storyThe explanation makes the need for another measurement concrete.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Test SimPEG. Laplace built a SimPEG workflow, starting with numerical checks and synthetic magnetic examples before moving to a three-dimensional terrain model.
Build terrain model. The Mount St Helens example uses NOAA ETOPO terrain and a specified IGRF field, but its subsurface bodies and magnetic anomaly are synthetic.
Compare inversions. A smooth and a compact inversion both fit the constructed signal while distributing susceptibility differently underground.
Explain uncertainty. Original figures and movies visualize what changes between the models. Review corrected a misfit-target definition and an earlier illustrative animation trace.
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
08h 52m 41sCalendar span of the conversation
32mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
Terrain is real; the magnetic observations and buried structures are synthetic.
The reconstruction depends on the specified field, geometry and inversion assumptions.
Misfit ratios measure fit relative to an assumed noise model, not the probability that the geology is correct.
The supplied archive is a partial set of the artifact records.
The next useful decision
Add an independent subsurface constraint or a survey with different sensitivity before treating either reconstruction as unique geology.
Build a three-dimensional gravity inversion, compare the recovered structure with a known target, and test what a good fit does and does not recover.Build a three-dimensional gravity inversion, compare the recovered structure with a known target, and test what a good fit does and does not recover.Build a three-dimensional gravity inversion, compare the recovered structure with a known target, and test what a good fit does and does not recover.
Research prompt↑
LLaplaceRecorded result
Mass comes close. Absolute depth remains unresolved.
After real-data access failed, a 529-station synthetic study recovered mass 5.02% above the constructed truth. A near-target data-misfit ratio of 1.012 still left the bed-depth geometry unresolved.
The observations and target geometry are synthetic, so their recovery errors do not establish field performance. The original figure’s BedMachine label refers to the stand-in used here, and absolute depth remains unresolved.
An edited brief introduces the recorded investigation. Read the source prompt below for its original context and later steering.
Read the research prompt
Original research prompt
use SemPeg, think about some kind of data you get from your earthdata API, and apply a 3D simulation by SImPeg trying to understand and explain the data
An integral formulation avoids unavailable sparse solvers; parameter searches test the reconstruction against known synthetic geometry.
A synthetic stand-in after real-data access failed. Eight iterations describes the accepted fit, not elapsed time. The recovered model still does not resolve absolute bed depth.
Watch the result Original session films
The fit and its blind spot1m 8.1s playback
Original explanation of a synthetic gravity inversion.
Playback length is separate from simulated time and the session span.
The work behind the result
Follow the investigation.
Record the failed access to the intended BedMachine data and use a clearly identified synthetic target.
Create the 49,376-cell model and 529 synthetic survey stations.
Resolve the thousand-fold unit issue and reject an optimizer exit code as sufficient evidence of convergence.
Score recovered mass, position and geometry against the constructed truth.
Deliver the fit and its limitations together instead of accepting a near-target misfit as proof of depth recovery.
Condensed from the recorded investigation, including later steering and review. Playback does not represent elapsed time.
529 stationsSynthetic observations used in the inverse problemSource
1.012Final data-misfit ratio, not reconstruction accuracySource
+5.02%Recovered mass relative to constructed truthSource
The output
The red and blue lines can disagree at depthOriginal file
Original figure retained unchanged. Its “BedMachine geometry” legend refers to the synthetic stand-in used in this run, not a downloaded real bed dataset.
How the investigation developed.
The user wanted real Earth data. Access to BedMachine was blocked, so the recorded study substituted synthetic geometry. That change determines what the result can claim.
01
Disclose the data substitution
The study uses a synthetic stand-in, not the requested real BedMachine dataset. The source report records the access problem.
02
Build and invert a gravity experiment
The model uses 49,376 active cells and 529 synthetic stations. Review corrected a thousand-fold unit issue and rejected an optimizer exit code as sufficient convergence evidence.
03
Check the answer against known synthetic truth
The recovered mass is about 5.02% above the constructed truth, and the along-axis position is close, but the bed-depth geometry remains unresolved.
04
Deliver both fit and failure
The report, scorecard, figures and movie show why a near-target data misfit is insufficient for a trustworthy depth estimate.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Acquire data
→
Task 2Build gravity model
→
Task 3Invert observations
→
Task 4Check geometry
→
Task 5Prepare a handoff
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Disclose stand-inRun gravity inversionCheck known truthExplain depth limits
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
Troubleshooting connected to interpretationUnit, optimizer and regularization issues are recorded with their scientific consequences.
Failure becomes useful evidenceThe comparison exposes unresolved depth even when the data fit looks good.
Reusable diagnostic handoffA scorecard, sections, report and movie preserve the result and its limits.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Disclose stand-in. The study uses a synthetic stand-in, not the requested real BedMachine dataset. The source report records the access problem.
Run gravity inversion. The model uses 49,376 active cells and 529 synthetic stations. Review corrected a thousand-fold unit issue and rejected an optimizer exit code as sufficient convergence evidence.
Check known truth. The recovered mass is about 5.02% above the constructed truth, and the along-axis position is close, but the bed-depth geometry remains unresolved.
Explain depth limits. The report, scorecard, figures and movie show why a near-target data misfit is insufficient for a trustworthy depth estimate.
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
01h 40m 19sCalendar span of the conversation
25mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
The requested real-data acquisition did not succeed; the demonstrated study is synthetic.
Matching the data does not establish bed-depth recovery. Residual bias also remains in the scorecard.
Mass and position errors concern this chosen synthetic truth and noise model, not field performance.
The original figure retains a misleading BedMachine label, explicitly qualified here.
The next useful decision
Obtain the intended real dataset, add independent depth information and repeat the inversion with an appropriate uncertainty analysis.
Model a supersonic gas eductor in OpenFOAM, diagnose solver failure, and check convergence and mass balance before accepting an entrainment ratio.Model a supersonic gas eductor in OpenFOAM, diagnose solver failure, and check convergence and mass balance before accepting an entrainment ratio.Model a supersonic gas eductor in OpenFOAM, diagnose solver failure, and check convergence and mass balance before accepting an entrainment ratio.
Research prompt↑
LLaplaceRecorded result
A coarse test weakens the mesh-only diagnosis.
A 51,300-cell case also fails, challenging the explanation that fine-grid geometry alone caused the problem. The later run still has unacceptable residuals and roughly 50% mass imbalance, so no entrainment ratio is accepted.
The CFD investigation remains unresolved and has no accepted entrainment result. The proposed very large remesh was not executed, and the transient-solver alternative was not demonstrated successfully.
Original diagnostic figure. Grouped early-failure bars are representative; exact early iteration counts vary. Longer survival does not establish convergence.
How the investigation developed.
A difficult compressible-flow setup can tempt a team to invest in larger meshes before isolating the actual failure.
01
Build the OpenFOAM setup
The record develops a specialist and a steady compressible RANS case with a k–ω SST turbulence model.
02
Challenge the mesh explanation
A 51,300-cell coarse case also fails, weakening the claim that fine-grid geometry alone explains the problem. The proposed very large remesh was not executed.
03
Improve numerical survival without accepting the answer
After revised turbulence initialization, one reported run reaches about 1,150 iterations but still fails. Residuals and mass balance remain unacceptable.
04
Preserve the diagnosis and next proposal
The final staged case has 410,400 cells. A transient solver and inlet-boundary revision are proposed next, not demonstrated as successful.
How Laplace carried the work
Direct the investigation. Inspect the work.
Laplace carries technical execution while researchers set the question, steer the study, and evaluate the evidence.
A team-managed workflowIllustrative workflow with existing tools
Task 1Define the flow
→
Task 2Mesh the geometry
→
Task 3Configure solver
→
Task 4Diagnose instability
→
Task 5Plan the next test
The team coordinates tools, context, and revisions across the study.
With LaplaceTechnical work demonstrated in these studies
HUMANBrief + steer
Laplace carries the technical work
Build flow caseTest mesh hypothesisDiagnose failed runPropose bounded test
↺ Run → inspect → revise, with researcher steering
HUMANReview + decide
An expensive branch challengedA failed coarse run weakened the case for the proposed large remesh.
False success rejectedIteration count and optimizer survival are separated from physical convergence.
A bounded next experimentThe handoff identifies an unresolved result and a specific next test.
Illustrates work ownership. Box widths are schematic; human time saved was not measured.
Inspect the work inside the Laplace block
Build flow case. The record develops a specialist and a steady compressible RANS case with a k–ω SST turbulence model.
Test mesh hypothesis. A 51,300-cell coarse case also fails, weakening the claim that fine-grid geometry alone explains the problem. The proposed very large remesh was not executed.
Diagnose failed run. After revised turbulence initialization, one reported run reaches about 1,150 iterations but still fails. Residuals and mass balance remain unacceptable.
Propose bounded test. The final staged case has 410,400 cells. A transient solver and inlet-boundary revision are proposed next, not demonstrated as successful.
These investigations often continued across separate visits. The first and last messages do not measure continuous work.
14h 25m 04sCalendar span of the conversation
53mCombined child-agent windows, with overlapping intervals counted once
Agent windows can include waiting and omit work in the main conversation. They are not a measure of active human work, total compute or time saved. The exports do not provide a reliable labour clock.
Scientific assumptions and limitations
The conversation is marked completed, but the CFD investigation is unresolved. No entrainment ratio is accepted.
The source report contains earlier hypotheses alongside later addenda; the later diagnostic evidence weakens the initial mesh-only explanation.
The transient-solver alternative is a proposal, not an executed successful follow-on.
Source review raised compute-authorization issues. This record is not proof of unattended spend control.
The next useful decision
Review the boundary conditions and run a bounded transient test with explicit convergence and mass-balance criteria before accepting performance.
Each study connects an edited research brief to the recorded work, its numerical evidence and the questions that remain open.
Numerical results with their limits
Synthetic observations, reduced models and comparisons between solvers are identified in the study. Numerical agreement does not by itself establish physical validation.
A focused technical handoff
Explore selected tables, figures, movies and scientific Python scripts. The public evidence summaries are curated explanations. Some original inputs and dependencies are unavailable, so the downloads are not complete reproducibility packages.